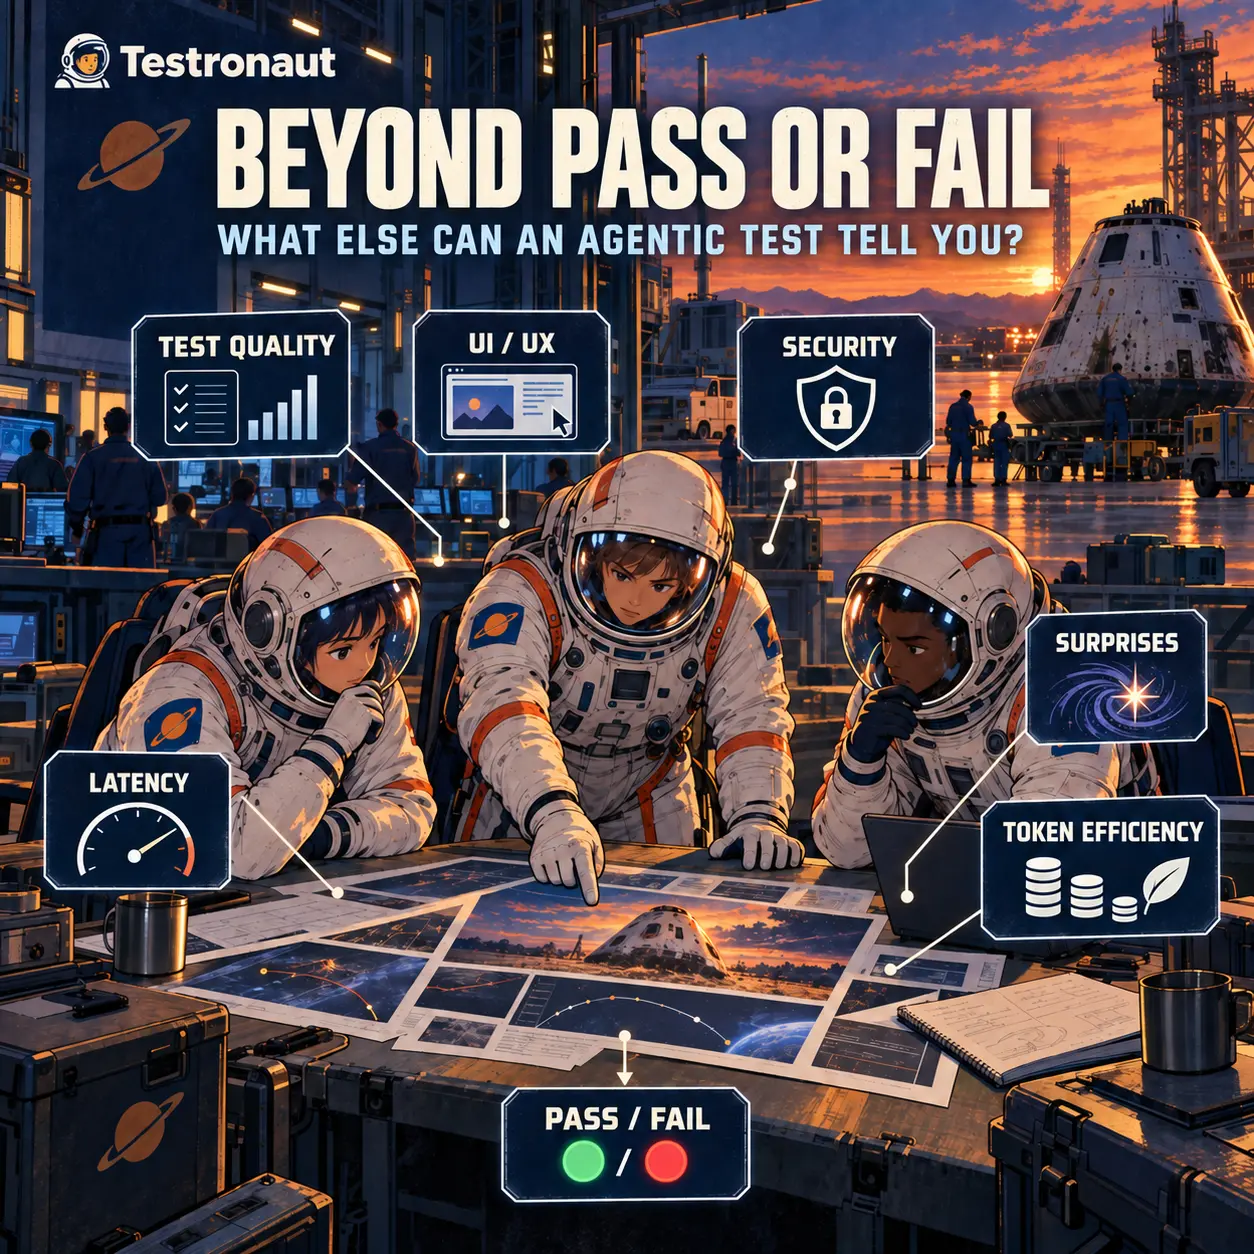
Most automated tests are designed to answer a simple question: did the test pass or fail?
Pass...
Or fail...
That's all!
And this is usually exactly what we want. A test should not pause after every run to offer opinions about the architecture. It should verify an expected result consistently.
But agentic end-to-end tests are different. The agent is already interpreting the interface, choosing actions, recovering from small surprises, and deciding whether the user’s goal was achieved.
A pass or fail result captures the destination, but it can leave a surprising amount of information about the journey behind.
I recently saw an interesting pattern in an example mission collection. The collection had a shared policy file containing prompt snippets that were applied across its missions. One snippet in particular asked the agent to look back at the completed run and provide feedback about the mission itself, the places it stumbled, and configuration changes that might make future runs more effective.
This changed how I thought about the output of an agentic test.
What if pass/fail is not the only useful thing the test can tell us?
A test run contains more than its result
A deterministic test is good at checking the expectations we remembered to encode.
An agentic test can verify those expectations while also noticing things we did not know to ask about.
For example, a mission might successfully complete a checkout flow but still observe that:
- Two buttons had nearly identical labels.
- A loading transition provided no feedback for several seconds.
- The agent inspected the same part of the page repeatedly because the state was unclear.
- A confirmation appeared somewhere unexpected.
- The mission wording allowed two reasonable interpretations.
- The run required far more tool calls than similar missions.
None of those observations necessarily means the mission failed. They may still be valuable signals about the product, the mission, or how the agent was configured.
That suggests a richer question than “Did it pass?”
What happened during the journey, and is any of it worth investigating?
Looking beyond pass or fail
There are several lenses an agent can use when reviewing a completed mission.
Test quality
Was the mission clear? Did it contain missing assumptions, redundant steps, or assertions that were too weak to prove the intended outcome?
The agent is in a useful position to answer this because it just attempted to follow the instructions. Hesitation, repeated interpretation, and unintended paths can reveal weaknesses in the mission authoring (the prompts).
UI and UX
Did labels make sense? Was the next action clear? Did the interface provide useful feedback after an action? Were controls difficult to distinguish or interact with?
These are observations rather than a replacement for user research or an accessibility audit. Still, they can point a team toward friction that a selector-based script would silently step through.
Security
Did the run encounter unexpected access, sensitive information in the interface, or behaviour that appeared unsafe?
An agent should not declare a vulnerability based on a single observation. It can, however, flag evidence that deserves validation by a person or a purpose-built security test.
Latency
Did a response or transition take noticeably longer than expected? Did the delay affect the user journey or cause the agent to retry?
This is not a substitute for instrumented performance testing. It is a way to notice when perceived performance becomes part of the experience being tested.
Surprises
Did the application enter a state the mission did not anticipate? Was there an alternate path that still achieved the goal? Did a modal, redirect, or notification appear unexpectedly?
This is where agentic testing can be particularly interesting. A deterministic test usually needs us to describe the surprise before it can look for it. An agent has some ability to recognize that the observed journey differs from the expected one.
Token efficiency
Where did the agent spend its effort? Did it repeatedly inspect the DOM, take unnecessary screenshots, retry the same action, or carry context that did not help complete the mission?
If agentic tests are going to earn their place near the top of the testing pyramid, we should evaluate not only whether they work, but whether they use their expensive resources well.
Is this a self-improving LLM?
Not exactly...
Perhaps we'll have an LLM truly capable of Recursive Self-Improvement (RSI) in the future, but the underlying model weights are not improving from run to run.
The testing system around the model can improve, though.
Each execution produces evidence. A reflection policy turns some of that evidence into structured recommendations. A human or controlled automation can review those recommendations, update the mission or configuration, and compare the next run against the previous one.
In a nutshell:
- Run the tests.
- Verify the expected outcome.
- Review the journey for useful signals.
- Propose a bounded set of improvements.
- Review and version those changes.
- Measure whether the next run is actually better.
That is less like a model teaching itself and more like a test suite participating in its own retrospective.
Reflection has a token bill
There is an obvious catch: reflection is not free.
Asking an agent to deeply critique every aspect of every successful mission can turn a useful idea into another source of token waste. This builds on the same principle I explored in Don’t Solve a $10 Testing Problem With $1,000 of Tokens: expensive tests should be reserved for expensive questions.
The same rule should apply inside an agentic test. Reflection should have a budget and a reason to exist.
Some practical controls include:
- Keep routine feedback short and structured.
- Limit the number of findings produced by one run.
- Require evidence for every observation.
- Allow the agent to report that it found nothing meaningful.
- Trigger deeper reflection after failures, retries, unexpected states, or unusually expensive runs.
- Sample successful missions rather than deeply reviewing every success.
- Compare accepted recommendations against later cost and reliability data.
- Don't ask for feedback on every test, and limit feedback cycles to avoid diminishing returns.
The goal is not to make the agent talk more. The goal is to extract enough useful evidence to make future runs better.
Applying the idea to Testronaut missions
I added a working version of this pattern to the public testronaut-examples repository.
The shared missions/policies.js file contains a screenshot policy and a mission feedback policy. Missions use a small helper to append those policies consistently:
import { applyMissionPolicies } from './policies.js';

export const loginMission = applyMissionPolicies(`
  Visit the login page and complete the expected journey.
  Report SUCCESS or FAILURE with evidence.
`);
The feedback policy asks the agent to consider the six lenses above, but it also places boundaries around the response:
- Keep the mission result separate from the review.
- Report only evidence observed during the run.
- Return no more than three findings.
- Include the observation, evidence, confidence, and suggested follow-up.
- Report “No additional findings” when there is nothing useful to add.
- Never weaken an assertion or automatically change a mission.
A successful mission might therefore produce an output shaped like this:
RESULT: SUCCESS

MISSION REVIEW
1. UI / UX
   Observation: The submission did not provide immediate visible feedback.
   Evidence: The agent waited and reinspected the page before the success notice appeared.
   Confidence: Medium
   Suggested follow-up: Confirm whether a loading or pending state should be displayed.

2. TOKEN EFFICIENCY
   Observation: The same region was inspected three times while waiting.
   Evidence: Repeated inspection occurred before the final state became visible.
   Confidence: High
   Suggested follow-up: Consider a more specific wait condition in the mission.
The mission still passed. The additional observations become leads that a human can accept, reject, or investigate.
Do not let the agent grade its own homework
There is a risk in asking an agent to review a test it just performed. The easiest recommendation may be to weaken the assertion, broaden the acceptable outcome, or rewrite the mission so that the observed behaviour counts as success.
That would make the test easier to pass without making the product better.
Recommendations should therefore be treated like proposed code changes:
- Preserve the evidence behind the recommendation.
- Require review before changing mission expectations.
- Keep changes in version control.
- Rerun the mission after the change.
- Compare reliability, cost, and coverage before changing it more permanently.
- Use dedicated tools to validate security, accessibility, and performance findings.
The agent can identify a possible improvement. It should not be the sole authority deciding that the improvement is correct.
The test can become an intelligent probe
Agentic testing is often described in terms of flexibility: the agent can navigate a changing interface without depending entirely on brittle selectors.
That is useful, but it may not be the most interesting part.
An agentic test can also act as an intelligent probe. It can verify the expected outcome while collecting evidence about the product, the mission, and the testing process itself. With a bounded feedback policy, every run has the potential to improve how the next mission is authored, configured, and evaluated.
Pass or fail still matters. It just may not be the only signal worth bringing back from the mission.
Or, as written by author Ursula K. Le Guin in her 1969 sci-fi novel The Left Hand of Darkness:
It is good to have an end to journey towards; but it is the journey that matters, in the end.